What the trace doesn’t say
On understanding AI agents from the data they produce
“Automation can make the difficult parts of the human operator’s task more difficult.”
— Lisanne Bainbridge, “Ironies of Automation” (1983)
Picture a meeting-room table in a New York office, covered in devices. Laptops and phones, each one moving data, usually more than one device per person seated at the table. One person is sharing a screen to the display at the end of the room. Someone else is presenting to remote colleagues. The rest are each doing something else, often several things. Every one of those devices is on Wi-Fi.
At JPMorgan Chase, I founded the research function for the firm’s new headquarters at 270 Park Avenue and its data-rich workspace technology. The building wasn’t finished while I did this work, so the research ran in the offices people were already using, and fed into the design of the new one. Leadership assumed that soft seating, the lounges and open areas, would drive demand for Wi-Fi. I sourced access-point and network logs from the New York offices and built heatmaps by zone and peak time. The heaviest use was in conference rooms and at desks that were already wired.
The logs settled where the demand was. They couldn’t say what it was. That took observation. The meeting-room traffic was work: a table of separate devices, some feeding a shared screen and people on a call, some holding notes and spreadsheets from which people spoke. The traffic in soft seating, once you watched it, made more sense as people watching TikTok on their lunch breaks. Both showed up as the same thing in the logs: data moving. The firm invested in the network at 270 Park around where and how people actually worked.
The trace is an index
Linguistic anthropologists have a useful word for what those logs were. An index is a sign that points to something because the two occur together, in space, in time or in context. Smoke and fire are the classic example, but so are the word “here” and the place it’s said, an accent and the region it comes from. Cause is only one kind of co-occurrence, and often hard to tell apart from the others. An index is good evidence that what it usually goes with is there too. It doesn’t tell you what their going together means.
An AI agent’s trace is an index in exactly this sense. An agent is software that takes a goal, breaks it into steps and carries them out with some independence: calling a model, searching, running code, using tools. Most observability tools record its work the same way. A trace is one end-to-end run, made of spans: timed steps nested inside one another, one for each model call, tool call or handoff between agents, each with its inputs and outputs, duration, token count and cost (OpenAI, Arize Phoenix). It is a faithful record of what the agent did.
The people who run agents bring four questions to that record. What did it do? Did it work? What did it cost? When should I step in? The trace answers the first. The other three are questions about meaning, and the answers mostly live somewhere else.
Toadstools and mycelium
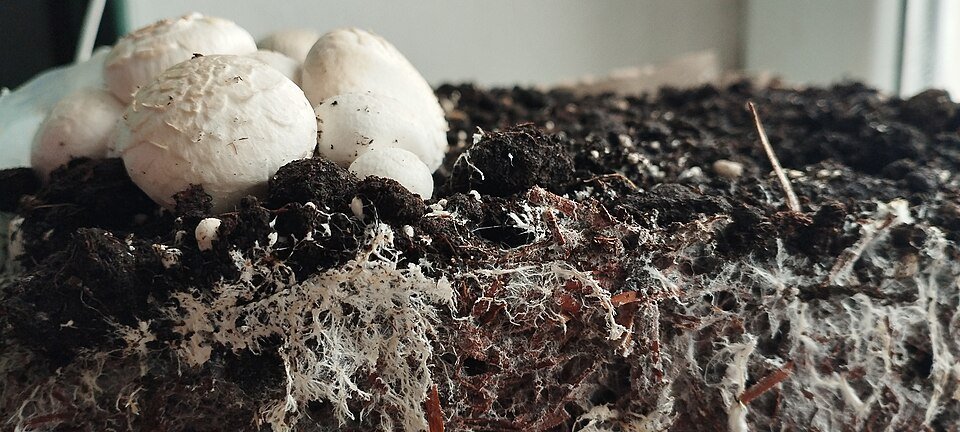
In my dissertation, on hidden networks of exchange in Dakar, I borrowed the image of a fungal fairy ring. Above ground you see a circle of toadstools, as if each had decided separately to stand there. The organism is underground: a mass of threads, the mycelium, of which the toadstools are only the visible fruit.
A trace is the toadstool. What makes an agent trustworthy grows underground. “Did it work?” depends on what the run was for and who relies on it, and those standards are often settled only in use. Researchers studying how developers grade model outputs found that people need criteria to judge outputs, but judging outputs is how they work out the criteria (Shankar et al. 2024). “What did it cost?” includes the afternoon an engineer spends rerunning a job to see whether a failure repeats, which no token count records. “When should I step in?” depends on stakes and on who will be blamed, which are organizational facts. Bainbridge’s irony applies: automation leaves people the hardest part of the job, taking over when things go wrong, while wearing down the skills they need to do it. Madeleine Clare Elish later showed that when automated systems fail, responsibility tends to land on the person with the least control, in what she calls a “moral crumple zone” (Elish 2019).
In Dakar, the hidden exchanges made each woman appear to act alone; her public strength was the visible sum of ties no one else could see. Agents get the same treatment. When the checking, rerunning and judging go unrecorded, the agent appears to have done the work by itself, and the people who made it trustworthy drop out of the account. In a data-rich environment, space, people and software are one system. The trace records the software and presents it as the whole.
More visibility isn’t the answer
The usual response is to show more: the agent’s plan, its steps, its reasoning. Agent builders recommend exactly this (Anthropic 2024). I argue it isn’t enough, and can make things worse. In one study, AI explanations made people more likely to accept a recommendation whether or not it was correct (Bansal et al. 2021).
Agents add a further twist, because much of what they show is language: plans, summaries, accounts of their own reasoning. Those work differently from the trace. The trace points to the work; the narration describes it, fluently and plausibly. Is this, like most human explanations of their own behavior, a post hoc just-so story (Nisbett and Wilson 1977; Turpin et al. 2023)? The reader has to keep track of which part of the screen is a record and which part is a story.
How people actually read agents
The people who debug agents are already doing something close to fieldwork. One practitioner guide starts with reading traces by hand, writing open-ended notes and sorting them into a taxonomy of failures: qualitative coding, in other words (Husain and Shankar 2025).
These questions come from my current ethnographic fieldwork with practitioners in agentic AI security. A problem at the center of that work is checking machine-generated code at all, when it arrives at a speed and volume no one can read line by line. Checking, comparing, rerunning, deciding to accept: that work happens beside the trace and mostly leaves no record in it. My own rule for research with AI tools is that AI can find, organize and check sources, but I verify every claim and build the argument, and nothing is cited to the AI itself (research-toolkit). The verifying is work. It is professional judgment, and it belongs in the picture.
Ethnography shows that work: what people do with agent data and how they do it. What they look at first, what they skip, what makes them stop trusting a run, how they check a result, when they escalate and to whom. A dashboard shows the toadstools. Ethnography maps the mycelium.
Designing for the reader
If people read traces, traces should be built as reading instruments. Record what a run was for next to what it did. Make human checking part of the record, so a team can see what was verified and by whom. Some tools now let experts score traces in annotation queues (LangSmith, Langfuse), but that is a grade added after the fact, not a record of the checking. The everyday checking, the rerun, the line-by-line read, the decision to accept, still happens outside the record. Count cost in people’s time as well as tokens. Design for the handoff, because the person reading a trace is often not the person who launched the agent.
None of that can be designed from telemetry alone. It starts with research on the people who run agents, and three questions:
- Who are they? Who reads agent data, and what are they responsible for when something goes wrong?
- What do they decide? Which decisions do they make from agent data: to accept a result, rerun it, roll it back, escalate, or stop the agent?
- Where do the signals fail them? Where do they leave the dashboard to check something by hand, and what are they looking for when they do?